I tested 15 AI video script skills. Luck mostly wins.
I gave the same news story to 15 AI video script tools (Claude skills, chains of skills and Custom GPTs) and asked each for a Reel voice-over. Two AI judges scored the scripts blind. A best tool exists, but the gap between tools is barely wider than the gap between two runs of the same model.
By Wael Aouididi · · 7 min read
In this article (7)
What I tested, and how
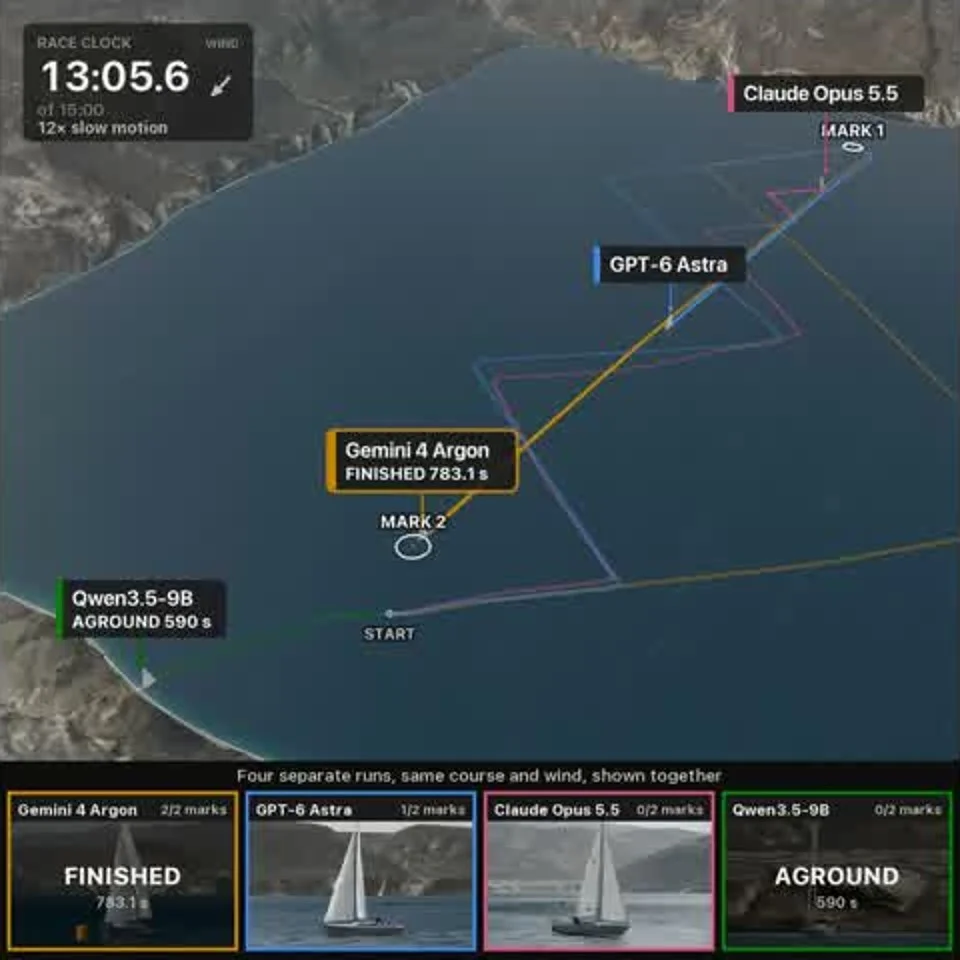
The starting point is a story from my daily AI news watch. On r/ClaudeAI, a developer had Claude Code build a sailing simulator, then handed the helm to four models: Opus, GPT-6 Astra, Gemini 4 Argon and a small Qwen. According to him, Argon wins at $0.78 per race, against $3.58 for Astra. But Argon only finishes one run out of two.
I asked each tool for the same deliverable: a French Reel voice-over, built from the same sheet of checked facts. Each Claude trial ran in a fresh Opus 5.5 session, with tools turned off and the skill's method given as text. The Custom GPTs got the same brief inside ChatGPT.
Two judges, Opus 5.5 and Fable 5.1, scored the scripts without knowing who wrote them, on 7 criteria out of 10: clarity, accuracy, hook, retention, how natural it sounds spoken, stakes and ending. A factual error caps accuracy at 3. There were three judging passes, then a final round where the 7 best tools wrote 3 scripts each, next to Opus alone, with no skill, as a control.
| What was measured | Value |
|---|---|
| Tools tested | 15 (13 Claude skills or chains, 2 Custom GPTs), plus Opus alone and 3 runs of Fable alone as controls |
| Scripts judged | 19 in the first rounds, then 24 in the three-trial round |
| Judging cost per pass | about $1.10 |
Why a single run proves nothing
In the first rounds, Melvynx came first with 8.57 and Vyral second with 8.32. A clean ranking. Except that I had also run Fable alone three times, with exactly the same prompt. Its three scripts scored 6.36, 7.86 and 6.93.
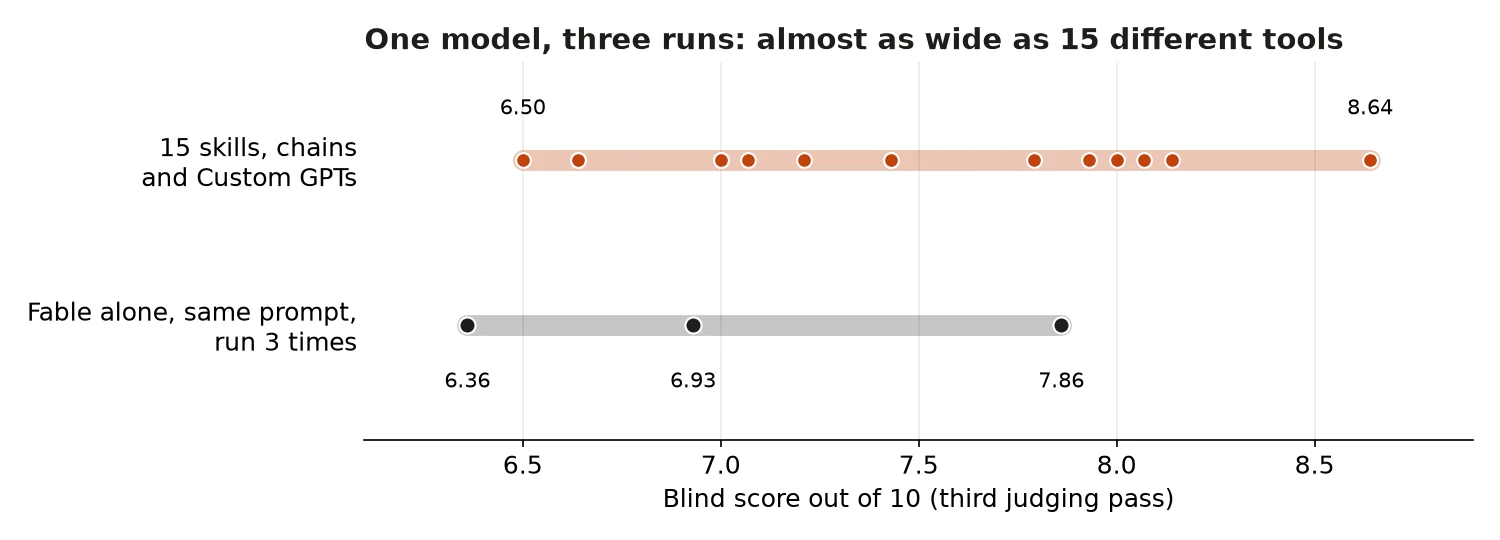
In other words, the same model with the same prompt moves from last place to sixth depending on the draw. The gap between its runs (1.50 points) is almost as wide as the gap between all the tools (1.71 points on combined scores). The judges add their own noise too: the same script, judged again, moves by about 0.24 points.
A ranking built on one run per tool measures luck as much as method. That is why I reran the finalists three times each.
The verdict after three trials per tool
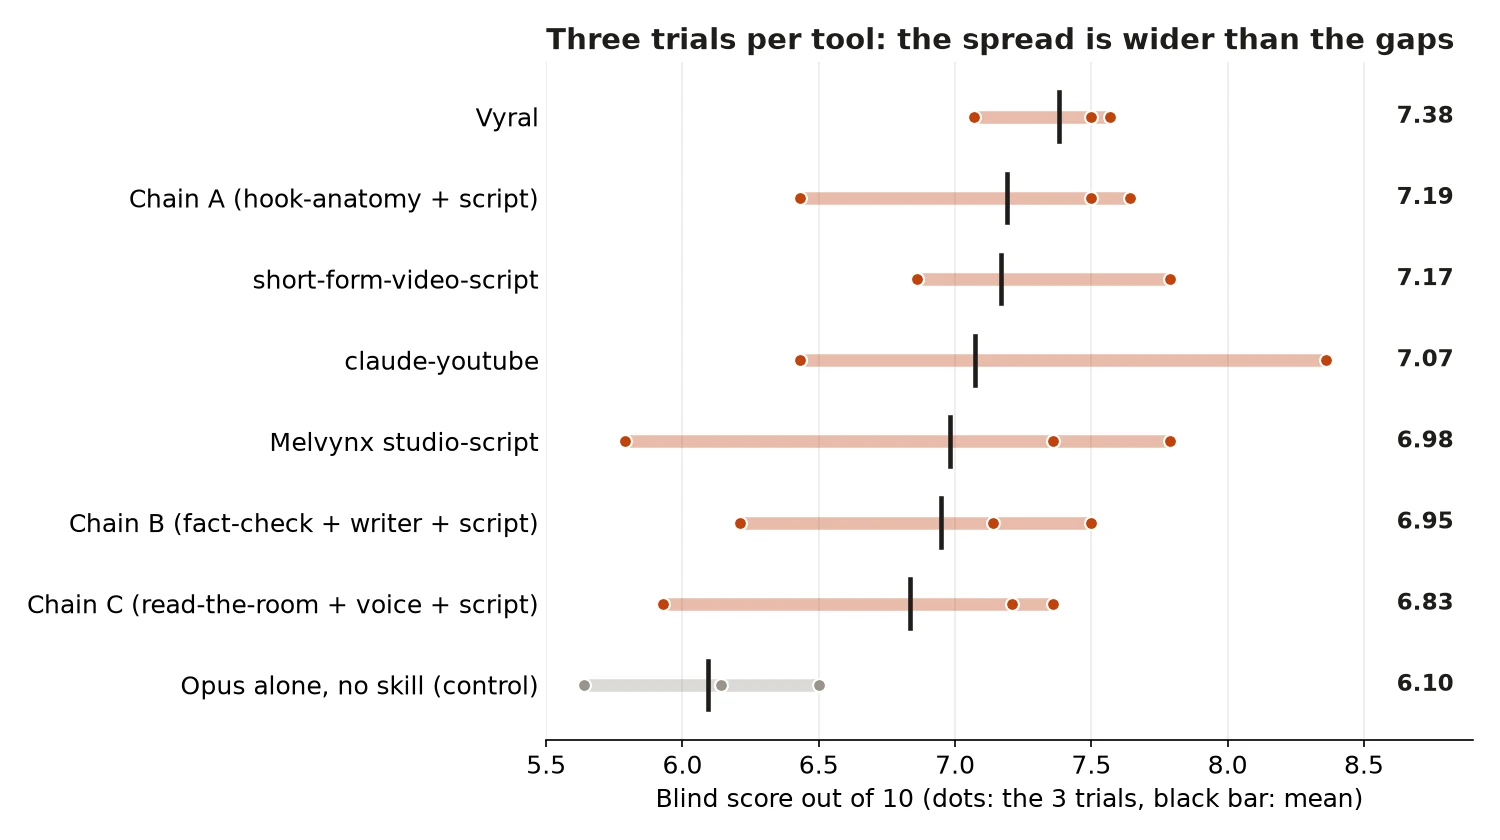
| Rank | Tool | Mean | Spread | Trials with an error |
|---|---|---|---|---|
| 1 | Vyral | 7.38 | 0.50 | 0 of 3 |
| 2 | Chain A (hook-anatomy, then short-form-video-script) | 7.19 | 1.21 | 1 of 3 |
| 3 | short-form-video-script | 7.17 | 0.93 | 1 of 3 |
| 4 | claude-youtube | 7.07 | 1.93 | 2 of 3 |
| 5 | Melvynx studio-script | 6.98 | 2.00 | 1 of 3 |
| 6 | Chain B (fact-check, then writer, then script) | 6.95 | 1.29 | 1 of 3 |
| 7 | Chain C (read-the-room, then voice-matching, then script) | 6.83 | 1.43 | 1 of 3 |
| 8 | Opus alone, no skill | 6.10 | 0.86 | 3 of 3 |
Three things stand out. Vyral is the only tool that is both on top and consistent, with no factual error. Melvynx, first on a single run, drops to fifth on average: its scripts range from 5.79 to 7.79. And from 2nd to 7th place, everything fits within 0.36 points, less than the gap between two runs of the same tool. Those places are not settled.
Scores in this round are lower than in earlier passes, because the judges were comparing 24 very similar scripts. Compare the ranks, not the numbers, from one round to the next.
What separates a good script from an average one
Skills clearly beat the control. Opus alone finishes last, at 6.10, and makes an error in each of its three runs. Every tool does better by 0.7 to 1.3 points. A serious skill is worth having, even if picking the best skill matters less than rerunning.
The most common error is the same almost everywhere: writing that "the cheapest one wins". The fact sheet gives no price for Opus or for Qwen, so nothing proves Gemini is the cheapest of the four. Other slips: promising "the rematch" when a commenter had only suggested it, or writing that Gemini "wins one race out of two".
Here is the opening of Vyral's best script, scored 7.57 (translated from French):
Four AIs at the helm of a sailboat. According to its creator, the winner costs four and a half times less. But there is a catch.
A concrete tension, credited to its source, and a promise the rest of the script keeps. Both judges only faulted its length. The control's worst script, scored 5.64, opens with no stakes ("Four AIs at the helm of a sailboat, and none of them gets advice") and states the $1.56 cost per finish as a fact, when it assumes every run is paid at the same rate.
What I would do this week
For a team that makes short videos with AI, the test gives a method more than a winner.
- Use a serious short-script skill rather than a bare prompt: the measured gain is 0.7 to 1.3 points out of 10.
- Generate 3 versions of the same script and keep the best one. It is the strongest lever measured here, and it costs a few cents.
- Have each version reviewed by an AI judge that gets the fact sheet, with one question: which sentence says more than the source?
- Then cut. Every script ran 121 to 180 words, while a 30 to 45 second voice-over holds 75 to 115.
- If you keep only one tool, Vyral was the most consistent in this test.
What we still do not know
This test covers a single news story, in French, for a single format. Another topic could change the order of the tools. The judges are two AIs from the same family as the script writers, and my own blind scores are not in the calculation yet. No script has been voiced yet, so real duration and one-listen comprehension are still to be measured.
Costs do not separate the tools either. In the last round, a single run cost $0.04 to $2.24, and Melvynx alone $0.05 to $0.73, depending on whether the cache was already built. It will take more runs to compare prices.
Next: voice the top 3, measure duration and comprehension, then rerun the test on a second news story before choosing a production tool.
And you: how many versions do you generate before you keep a script?
Sources and tools tested
Repositories and threads read on November 6 and 7, 2026.
- The news story: u/abhi3188's post on r/ClaudeAI and its video, source of the facts and of the opening image.
- Vyral, viral-short-form and viral-hooks: 1st after 3 trials.
- hook-anatomy, read-the-room, voice-matching (scrollmark): chains A and C.
- short-form-video-script (social-media-skills): 3rd, and the end of chain A.
- claude-youtube (AgriciDaniel): 4th.
- Melvynx, studio-script: 1st on one run, 5th on three.
- fact-check-workflow (jamditis), content-research-writer (ComposioHQ) and short-form-script (mohitagw15856): chain B.
- Tested in the first rounds, not in the final: marketingskills (coreyhaines31), video-content-strategist (alirezarezvani), youtube-agent-skill, avoid-ai-writing, and two Custom GPTs, Reel Script GPT and Video Maker AI.
Wael Aouididi, yoursaasgrowth
Want an AI content workflow that holds up?
If you are building video or content production with AI, I can help you set up the tools, the checks and the tests worth running first.
Book a 20-min GTM Audit